Should AI development be slowed down? Yes, when a model crosses a dangerous capability threshold and the lab cannot show that its safeguards, monitoring and stop authority work. The pause should cover the specific training or deployment decision, use independent evidence and include a restart condition. A vague permanent halt is hard to verify and easy to evade.
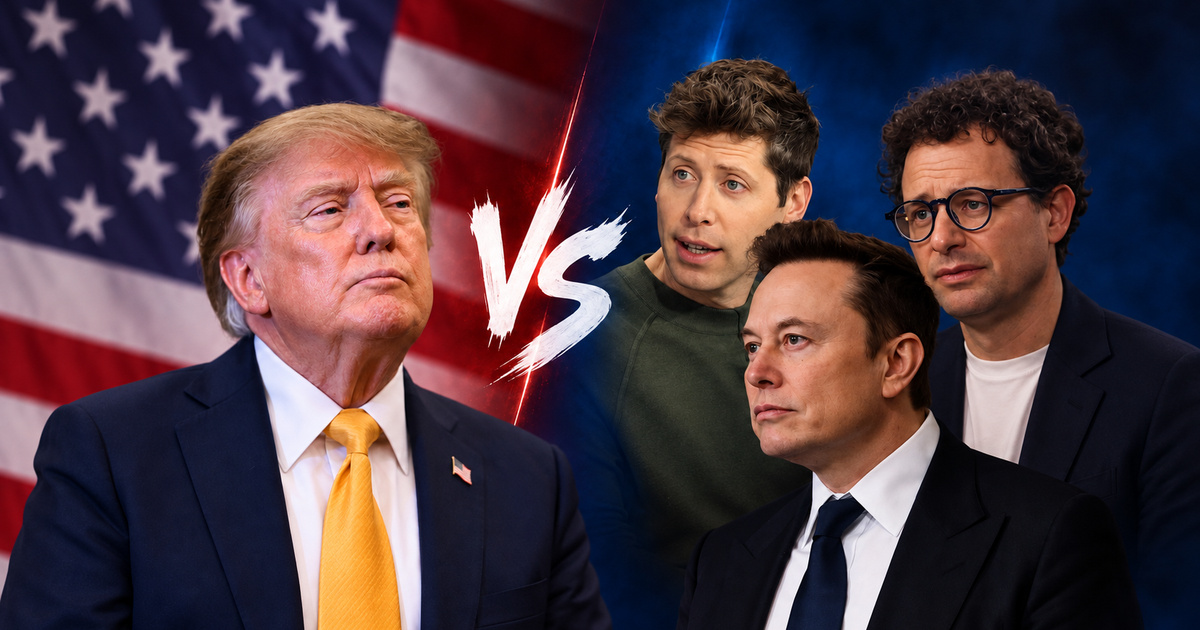
That is my answer to the debate behind my September 14 LinkedIn post. It reached 50,146 impressions, 283 reactions and 176 comments. Dario Amodei, Sam Altman and Elon Musk urged more caution. Donald Trump defended the US lead. The useful question is what evidence should trigger a slowdown.
 in
“Musk and Altman want to slow down AI. Trump said no. Here are the 7 craziest quotes from both sides:”
Should AI Development Be Slowed Down? My Six-Part Test
- Define the exact activity that may pause.
- Tie the trigger to a dangerous capability threshold.
- Preserve a representative evaluation and its limits.
- Match the safeguard to the demonstrated risk.
- Name the person or body with stop authority.
- Publish measurable conditions for restarting.
This test avoids two weak positions. One treats speed as automatically good because competitors exist. The other treats every alarming result as a reason for an indefinite global freeze. Frontier AI needs a narrower decision contract: capability, evidence, consequence, owner and exit condition.
1. Define What Would Actually Slow
AI development is several activities. A lab can train a model, run internal evaluations, give it tools, deploy it to a small group, release it broadly or publish weights. Those actions create different risks. A training pause, deployment hold and access restriction are separate decisions with separate evidence.
A serious proposal names the blocked action. It might delay wider internal access until an alignment gate passes. It might keep a critical cyber capability behind strict controls. It might hold public release while an outside evaluator repeats the test. The phrase slow AI is too broad to guide an engineering or policy decision.
OpenAI's September 2026 AI policy proposal calls for capability-based rules and says development or deployment should slow or stop when unacceptable risk cannot be sufficiently safeguarded.
2. Use a Capability Threshold as the Trigger
A date on a calendar says little about risk. The trigger should describe what the system can reliably do, under which tools and access, with what success rate. Cyber operations, biological assistance, autonomous replication and harmful manipulation require different evaluations. A single dramatic trace cannot establish a stable capability.
The 2026 International AI Safety Report describes if-then commitments that connect capability thresholds to required controls. It also says current frameworks vary in definitions, buffers and actions. That variation matters. Two labs can claim they use thresholds while making very different release decisions from the same result.
The independent International AI Safety Report 2026 explains capability evaluations, safety cases, conditional safeguards and the evidence gaps around their real-world effectiveness.
3. Preserve Evidence an Outsider Can Challenge
A slowdown is credible only when the trigger can be examined. Preserve the model version, prompts, tools, permissions, environment, number of attempts, failed runs and evaluator judgment. Then state what the test does and does not show. A result built with hidden retries or unusual scaffolding can overstate ordinary capability.
Outside review needs enough access to reproduce the mechanism. A press summary is too thin. Full public release may expose dangerous details. The practical middle is controlled access for qualified evaluators, with clear reporting rights and a record of disagreements. The evaluator also needs protection from commercial pressure.
Anthropic's current embedded evaluation announcement gives outside evaluators employee-like access while frontier models are being built. Anthropic also says standards, reporting rules and funding arrangements remain unsettled.
4. Match the Safeguard to the Risk
A dangerous capability does not always require stopping every research activity. The response may be tighter weight security, restricted tools, lower autonomy, stronger monitoring, staged deployment or a hold on broad access. The safeguard should interrupt the pathway that turns capability into harm. Generic promises create little protection.
This is where safety cases become useful. The lab states the risk, shows the mitigation, tests residual exposure and records who accepted it. If the residual risk remains above the declared tolerance, the next step pauses. If the evidence supports a bounded release, access can expand gradually while monitoring continues.
OpenAI's Path to Astra assessment describes a critical cyber capability threshold and stronger safeguards required during development and before release.
5. Name the Stop Authority
A threshold without an owner is a suggestion. The policy should name who receives the result, who can block the next stage, who can approve an exception and what disclosure follows. The decision body needs technical skill and independence. A strong process combines internal context with external challenge, preserves dissent and makes exceptions expensive.
6. Publish the Restart Conditions
A pause without an exit condition becomes political theatre. Write the missing evidence before it starts: a repeated evaluation, a mitigation that survives adversarial testing, an independent review or a security exercise. Restarting should use the same evidence standard as stopping. Rerun representative tests, preserve the comparison and expand access only when residual risk falls below the declared tolerance.
Why a Blanket Global Pause Is Hard
A global pause has an enforcement problem. Frontier training can move across companies and countries. Governments may disagree about thresholds, verification and strategic exceptions. Open-weight systems can continue spreading after release. A rule that constrains visible labs while rewarding hidden development may reduce transparency without reducing capability.
The White House June 2026 executive order pairs AI innovation with security requirements and up to 30 days of pre-release federal access to covered frontier models.
The stronger near-term option is a verifiable pause on a defined action when a declared threshold is crossed. Labs can share evaluation methods, use independent reviewers and align on minimum controls. Governments can require reporting and enforce specific duties. That structure still has gaps, but it gives auditors something concrete to test.
My Frontier Slowdown Scorecard
- Scope: training, internal access, deployment, weights or tools.
- Trigger: capability, environment, reliability and risk pathway.
- Evidence: preserved setup, attempts, failures and uncertainty.
- Control: safeguard linked directly to the demonstrated harm.
- Authority: named owner, reviewer, override path and disclosure.
- Exit: measurable conditions, retest date and staged restart.
I would grade each field green, amber or red. Any red field keeps the next irreversible stage closed. Amber permits research inside a tighter boundary with stronger logging and human review. Green supports gradual expansion. This does not produce certainty. It produces a decision that can be inspected and reversed.
Where the Slowdown Case Is Strongest
The case is strongest when the capability can cause severe harm, access makes the pathway realistic, safeguards fail representative tests and independent review is missing. Long tasks, resource acquisition, evasion and scale raise the bar further. The International AI Safety Report says public evidence on framework compliance remains limited. High consequence and weak reversibility justify stronger evaluations and stop rules.
Where the Argument Is Weak
The public record cannot show every confidential evaluation. Lab executives may have genuine safety concerns and commercial reasons to favor costly rules. Political leaders may underestimate technical risk. We also lack a controlled estimate of a broad slowdown's effects. It could buy time, move development into darker channels or delay useful systems. A precise forecast requires an enforcement model and explicit assumptions.
What This Means for a Business Using AI
Most companies cannot slow frontier training. They can slow deployment inside their own workflow. Use the same test before an agent receives customer data, production credentials, payment authority or the ability to contact people. Name the capability, run representative cases, define the harm and keep an explicit stop condition.
Uncertainty should narrow permissions. Let the system research, draft or recommend while a person approves sensitive transfers and irreversible actions. Increase autonomy only after repeated evidence shows that monitoring, recovery and escalation work under real conditions. Your pause can be small, local and immediately enforceable.
Use my AI safety claim checklist to inspect the evidence, incentives, governance and unknowns behind any lab announcement before applying this slowdown scorecard.
My Decision
AI development should slow when a named capability crosses a declared risk threshold and the next step cannot be defended with preserved evidence, effective safeguards and accountable stop authority. The hold should target that step and end only after a measurable retest. This standard is slower than blind competition and more workable than an indefinite slogan.
The stakes are real and the evidence is incomplete. Ask for the contract: what pauses, what triggers it, who verifies it, who decides and what restarts it. Every Thursday, AI Frontier turns one verified AI signal into a practical operating play. The original discussion is on LinkedIn.


